Skip to navigation

Responses API Example: Deepgram-Groq-Inworld

View as Markdown

For the complete documentation index, see llms.txt.

Overview

This full-cascade example demonstrates:

  1. A full cascade Voice AI pipeline with independent Speech-to-Text (STT), Large Language Model (LLM), and Text-to-Speech (TTS) components
  2. 3rd Party LLM use using OpenAI Compatibility mode in the VoxEngine OpenAI module
  3. Turn taking with barge-in and end-of-turn detection to keep interactions natural and responsive

This specific example uses Deepgram for STT with custom vocabulary, Groq’s OpenAI-compatible Responses API using llama-3.3-70b-versatile for the LLM, and Inworld for low-latency, streaming TTS. These can be changed out for any supported VoxEngine modules or external APIs as needed.

⬇️ Jump to the Full VoxEngine scenario.

Prerequisites

  • Store your Groq API key in Voximplant Secrets under GROQ_API_KEY.
  • The example imports Modules.Agentic and creates VoiceDSP directly; no preceding helper scenario is required.

How it works

  • Deepgram transcribes caller audio with interim and final transcripts.
  • Agentic.createVoiceDSP({ asr: stt, ... }) receives the same Deepgram ASR instance used for call media. It bundles VAD and Smart Turn. TurnStopped.content carries the latest transcript after the configured 0.3-second ASR grace window; the sample submits one request from that event.
  • The scenario sends completed user turns to Groq through OpenAI.createResponsesAPIClient({ baseUrl: "https://api.groq.com/openai/v1" }).
  • Caller audio is sent independently to Deepgram ASR and VoiceDSP. Response text deltas are streamed into Inworld TTS and played back into the call. Optional Inworld credentials can use Voximplant provider billing when omitted.
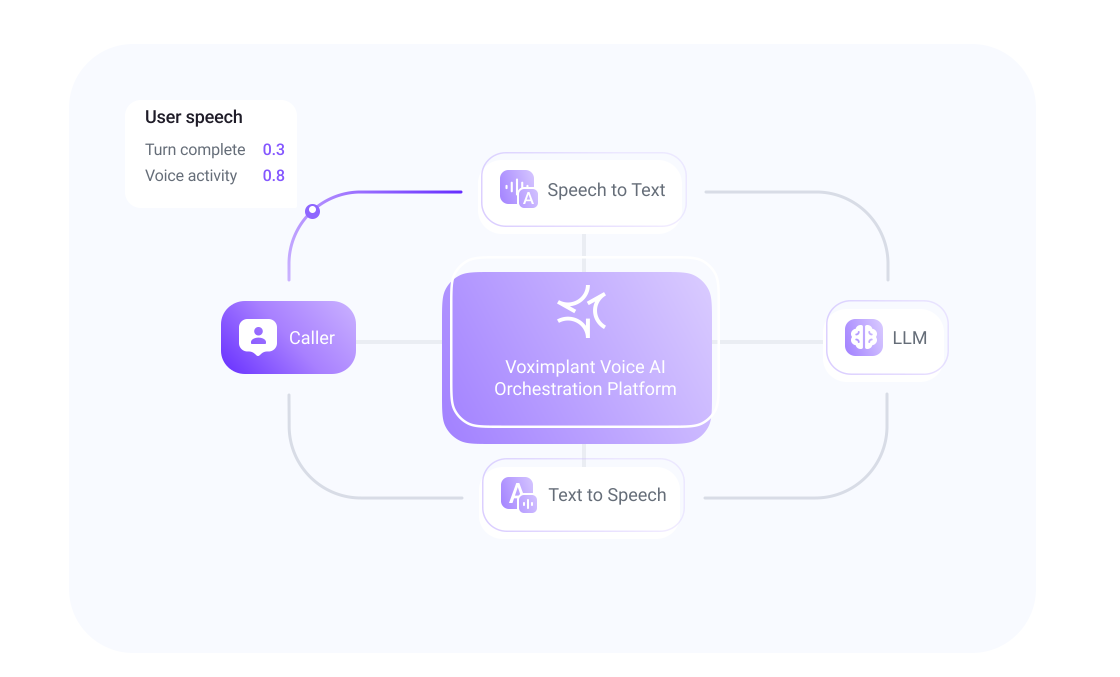
Full-cascade flow illustration

Full-cascade BYO LLM pattern

In a production full-cascade voice AI pipeline, you usually combine:

  1. STT for caller transcription.
  2. Turn-taking logic to decide when the caller has finished speaking.
  3. Chat Completions or Responses for the LLM.
  4. Realtime TTS for generated speech.
  5. Barge-in handling to stop agent speech when the caller interrupts.

The complete scenario below implements this flow with VoiceDSP. TurnStarted clears TTS and marks pending LLM output as discarded. TurnStopped submits the transcript; TurnInferenceTriggered is logged rather than used for a second request because it carries no transcript. A newer completed user turn replaces the queued turn while an older Responses request completes silently. Both late text deltas and completion events from the interrupted response are ignored. The Responses adapter has no per-response cancellation method; provider inference is not cancelled.

The first accepted text delta signals signalAssistantTurnStarted(). After text completion and the next AudioChunksPlaybackFinished, the scenario calls signalAssistantTurnEnded(). Intermediate playback completions and ResponseCompleted do not mark the assistant idle. TurnIdle terminates only when no user turn, request, or assistant playback is active.

On call failure, disconnect, ASR/Responses/VoiceDSP/TTS error, or the three-minute demo deadline, the sample closes its clients and stops ASR/TTS. Resources that finish asynchronous setup after hangup are closed immediately.

Notes

  • This example uses an OpenAI-compatible API, not OpenAI’s own hosted Responses API. The VoxEngine OpenAI module still works because the Groq endpoint follows the same request and event model closely enough for this flow.
  • Groq’s current Responses API support is still limited relative to OpenAI’s full stored-context flow. In practice, you should not assume support for features such as previous_response_id or storeContext. This example keeps each turn independent to stay simple and predictable.
  • If you need multi-turn memory with Groq, manage conversation history locally and resend the full structured input on each request.
  • The included prompt is intentionally short for example readability. Text-expecting models such as Llama usually behave better with a more explicit system prompt that tightly defines tone, grounding, brevity, ambiguity handling, and how to respond to partial caller fragments.
  • Configure bundled VAD, Smart Turn, transcript grace, interruption, and idle behavior through Agentic VoiceDSP. It is a VoxEngine module, so the scenario is self-contained.

More info

  • OpenAI module API: /api-reference/voxengine/openai
  • VoiceDSP API: /api-reference/voxengine/agentic/voice-dsp
  • VoiceDSP events: /api-reference/voxengine/agentic/voice-dsp-events
  • Inworld module API: /api-reference/voxengine/inworld
  • Deepgram ASR profile guide: /platform/voxengine/integrations

Full VoxEngine scenario

voxeengine-full-cascade-dg-groq-iw.js
/**
* Cascaded voice AI: Deepgram STT → Groq Responses → Inworld realtime TTS.
* Each request is independent; Groq does not support previous_response_id.
* VoiceDSP provides turn boundaries; no preceding helper scenario is required.
*/
require(Modules.Agentic);
require(Modules.ASR);
require(Modules.OpenAI);
require(Modules.Inworld);
const GROQ_MODEL = "llama-3.3-70b-versatile";
const SYSTEM_PROMPT = `
You are Voxi, a helpful phone assistant for Voximplant. Reply in English.
Keep responses short, polite, and telephony-friendly (usually one or two sentences).
`;
VoxEngine.addEventListener(AppEvents.CallAlerting, ({call}) => {
/** @type {ASR | undefined} */
let stt;
/** @type {OpenAI.ResponsesAPIClient | undefined} */
let responsesClient;
/** @type {Inworld.RealtimeTTSPlayer | undefined} */
let ttsPlayer;
/** @type {Agentic.VoiceDSP | undefined} */
let voiceDSP;
let finished = false;
let responsePending = false;
let discardResponse = false;
let queuedInput;
let userSpeaking = false;
let assistantSpeaking = false;
let textFinished = false;
let idleRearmTimer;
const terminate = () => {
if (finished) return;
finished = true;
clearTimeout(timeout);
clearTimeout(idleRearmTimer);
stt?.stop();
voiceDSP?.close();
ttsPlayer?.stop();
responsesClient?.close();
VoxEngine.terminate();
};
const timeout = setTimeout(terminate, 180000);
call.addEventListener(CallEvents.Disconnected, terminate);
call.addEventListener(CallEvents.Failed, terminate);
call.addEventListener(CallEvents.Connected, async () => {
try {
const groqApiKey = VoxEngine.getSecretValue("GROQ_API_KEY");
if (!groqApiKey) throw new Error("Create the GROQ_API_KEY Voximplant Secret before running this LLM example.");
stt = VoxEngine.createASR({
profile: ASRProfileList.Deepgram.en_US,
interimResults: true,
request: {language: "en-US", model: "nova-2-phonecall", keywords: ["Voximplant:4", "OpenAI:2"]},
});
stt.addEventListener(ASREvents.ASRError, (event) => {
Logger.write("===ASR.Error=== " + JSON.stringify(event));
terminate();
});
const responsesParameters = {
apiKey: groqApiKey,
baseUrl: "https://api.groq.com/openai/v1",
storeContext: false,
onWebSocketClose: (event) => {
Logger.write("===Groq.Responses.WebSocket.Close=== " + JSON.stringify(event));
terminate();
},
};
responsesClient = await OpenAI.createResponsesAPIClient(responsesParameters);
if (finished) { responsesClient.close(); return; }
// Optional Inworld API key: omit it to use Voximplant provider billing.
ttsPlayer = Inworld.createRealtimeTTSPlayer({
createContextParameters: {create: {
voiceId: "Ashley", modelId: "inworld-tts-1.5-mini", speakingRate: 1.1, temperature: 1.3,
}},
});
ttsPlayer.addEventListener(PlayerEvents.Error, (event) => {
Logger.write("===Groq.TTS.Error=== " + JSON.stringify(event));
terminate();
});
ttsPlayer.addEventListener(PlayerEvents.Started, () => {
if (finished || userSpeaking) return;
assistantSpeaking = true;
voiceDSP?.signalAssistantTurnStarted();
});
ttsPlayer.addEventListener(PlayerEvents.AudioChunksPlaybackFinished, (event) => {
if (finished) return;
Logger.write("===Groq.TTS.TTFB=== " + event.timeToFirstByte);
// Do not declare the assistant idle between chunks or at LLM completion.
if (textFinished && assistantSpeaking) {
assistantSpeaking = false;
voiceDSP.signalAssistantTurnEnded();
}
});
const requestResponse = (input) => {
if (finished) return;
// One response at a time: interrupted responses finish silently.
if (responsePending) { queuedInput = input; return; }
responsePending = true;
discardResponse = false;
responsesClient.createResponses({model: GROQ_MODEL, instructions: SYSTEM_PROMPT, input});
};
const responseFinished = () => {
if (finished) return;
responsePending = false;
if (queuedInput !== undefined) {
const input = queuedInput;
queuedInput = undefined;
requestResponse(input);
} else if (!assistantSpeaking) {
voiceDSP.signalAssistantTurnEnded();
}
};
voiceDSP = await Agentic.createVoiceDSP({
asr: stt,
vadParameters: {threshold: 0.5, minSilenceDurationMs: 350, speechPadMs: 10},
turnDetectorParameters: {threshold: 0.5, stopSecs: 3},
asrGraceTimeout: 0.3,
userTurnStopTimeout: 5,
userTurnIdleTimeout: 30,
startStrategies: [Agentic.VoiceDSPStrategies.createVADStart({enableInterruptions: true})],
stopStrategies: [Agentic.VoiceDSPStrategies.createTurnDetectorStop()],
});
if (finished) { voiceDSP.close(); return; }
voiceDSP.addEventListener(Agentic.VoiceDSPEvents.TurnStarted, (event) => {
if (finished) return;
userSpeaking = true;
clearTimeout(idleRearmTimer);
Logger.write("===USER TURN STARTED=== interrupted=" + event.interrupted);
// A user turn invalidates pending inference even before TTS has started.
discardResponse = true;
queuedInput = undefined;
textFinished = false;
ttsPlayer.clearBuffer();
assistantSpeaking = false;
voiceDSP.signalAssistantTurnEnded();
});
voiceDSP.addEventListener(Agentic.VoiceDSPEvents.TurnStopped, (event) => {
if (finished) return;
userSpeaking = false;
const input = event.content.trim();
Logger.write("===USER===> " + input + " transcript=" + event.transcriptState);
// TurnStopped carries the transcript; TurnInferenceTriggered does not.
if (input) requestResponse(input);
else if (!assistantSpeaking) {
// VoiceDSP resets its active turn after this callback returns.
clearTimeout(idleRearmTimer);
idleRearmTimer = setTimeout(() => {
if (!finished && !responsePending && !userSpeaking && !assistantSpeaking) {
voiceDSP.signalAssistantTurnEnded();
}
}, 0);
}
});
voiceDSP.addEventListener(Agentic.VoiceDSPEvents.TurnIdle, () => {
if (!finished && !responsePending && !userSpeaking && !assistantSpeaking) terminate();
});
voiceDSP.addEventListener(Agentic.VoiceDSPEvents.Error, (event) => {
Logger.write("===VoiceDSP.Error=== " + JSON.stringify(event));
terminate();
});
[Agentic.VoiceDSPEvents.TurnInferenceTriggered, Agentic.VoiceDSPEvents.TurnStopTimeout,
Agentic.VoiceDSPEvents.ConnectorInformation].forEach((eventName) => {
voiceDSP.addEventListener(eventName, (event) => {
Logger.write("===VoiceDSP " + eventName + "=== " + JSON.stringify(event));
});
});
responsesClient.addEventListener(OpenAI.ResponsesAPIEvents.ResponseTextDelta, (event) => {
const payload = /** @type {{delta?: string}} */ (event?.data?.payload || {});
const text = payload.delta;
if (finished || discardResponse || !responsePending || !text || userSpeaking) return;
textFinished = false;
if (!assistantSpeaking) {
assistantSpeaking = true;
voiceDSP.signalAssistantTurnStarted();
}
ttsPlayer.send({send_text: {text}});
});
responsesClient.addEventListener(OpenAI.ResponsesAPIEvents.ResponseTextDone, (event) => {
if (finished || discardResponse || !responsePending || userSpeaking) return;
const payload = /** @type {{text?: string}} */ (event?.data?.payload || {});
Logger.write("===AGENT===> " + payload.text);
textFinished = true;
ttsPlayer.send({flush_context: {}});
if (!assistantSpeaking) voiceDSP.signalAssistantTurnEnded();
});
responsesClient.addEventListener(OpenAI.ResponsesAPIEvents.ResponseCompleted, responseFinished);
[OpenAI.ResponsesAPIEvents.ResponseFailed, OpenAI.ResponsesAPIEvents.ResponseIncomplete,
OpenAI.ResponsesAPIEvents.ResponseError, OpenAI.ResponsesAPIEvents.ResponsesAPIError].forEach((eventName) => {
responsesClient.addEventListener(eventName, (event) => {
Logger.write("===Groq.Responses.Error=== " + JSON.stringify(event));
terminate();
});
});
[OpenAI.ResponsesAPIEvents.ResponseCreated, OpenAI.ResponsesAPIEvents.ResponseInProgress,
OpenAI.ResponsesAPIEvents.ResponseCompleted, OpenAI.ResponsesAPIEvents.ConnectorInformation,
OpenAI.ResponsesAPIEvents.Unknown, OpenAI.Events.WebSocketMediaStarted,
OpenAI.Events.WebSocketMediaEnded].forEach((eventName) => {
responsesClient.addEventListener(eventName, (event) => {
Logger.write("===Groq.Responses " + eventName + "=== " + JSON.stringify(event));
});
});
call.sendMediaTo(stt);
call.sendMediaTo(voiceDSP);
ttsPlayer.sendMediaTo(call);
requestResponse("Greet the caller briefly and ask how you can help.");
} catch (error) {
Logger.write("===Groq pipeline setup failed=== " + error);
terminate();
}
});
call.answer();
});